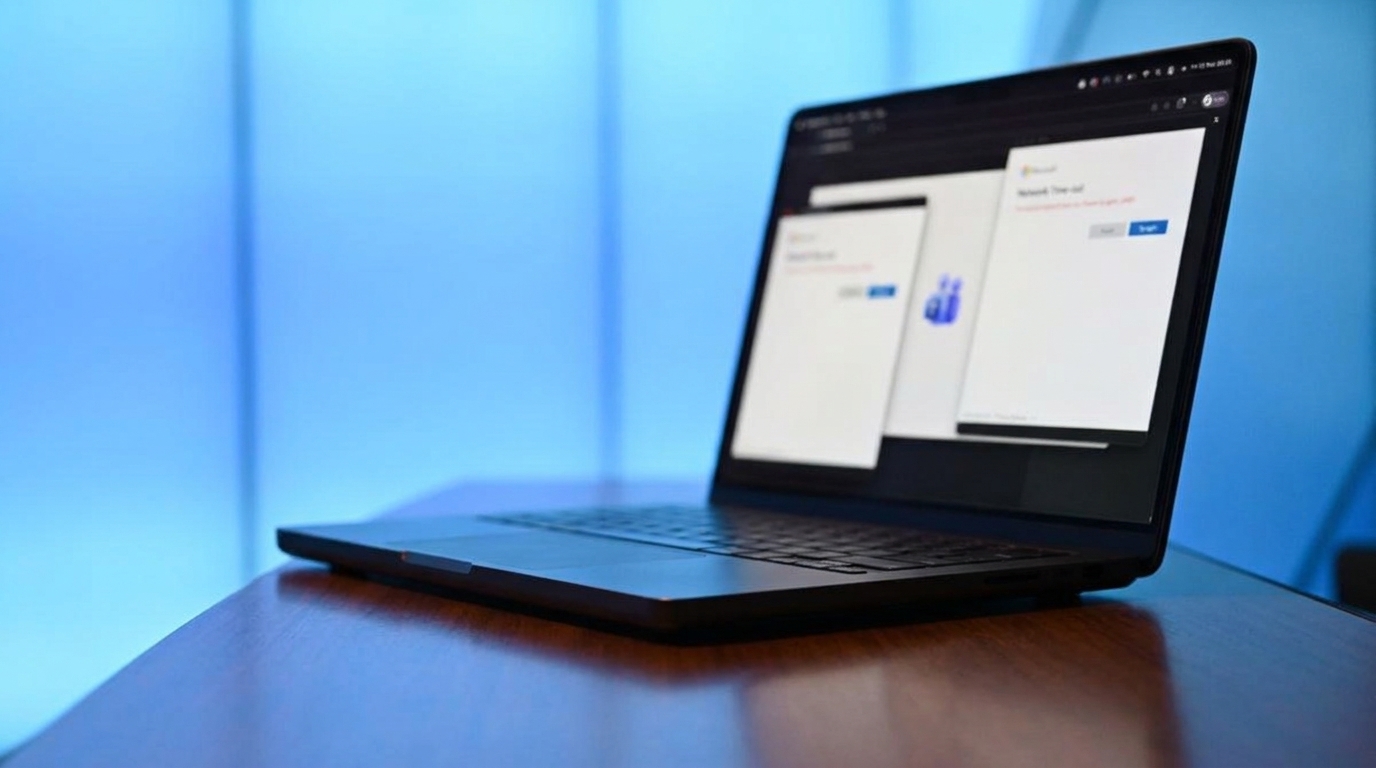
Disruptions across global communication channels stretched into a second consecutive day before network recovery took hold. BBC News reported that Microsoft issued a formal apology after widespread failures knocked out email and messaging tools for organizations worldwide. We've seen how sudden outages paralyze daily operations when administrative traffic halts without warning.
Key Takeaways
- Global messaging and email platforms suffered widespread interruptions across two consecutive days.
- Microsoft issued a formal apology and confirmed that network recovery operations made encouraging progress.
- Industry specialists warned that global administrative infrastructure depends too heavily on a handful of tech corporations.
- Operating independent secondary communication networks prevents administrative work from stopping during single-provider outages.
What Caused the Multi-Day Disruption Across Core Services?
Enterprise communication systems broke down when central cloud servers stopped processing routine messaging traffic and business correspondence. The New York Times reported that Microsoft experienced disruptions spanning two days across its primary email and collaborative platforms. When unified directory servers fail to route incoming credentials, connected software suites disconnect simultaneously and lock workforces out of internal channels.
Centralized architectures route data packets through common nodes to manage corporate security profiles. When an internal fault hits these central gateways, every linked service fails in tandem. You lose the ability to send urgent internal dispatches, dispatch calendar invitations, or confirm deliveries with external clients.
- Audit administrative channels: Map out every internal system that relies on a single authentication provider to identify operational single points of failure.
Why Does Reliance on Big Tech Providers Threaten Operations?
Consolidating international data workflows within a few dominant technology corporations leaves entire economic sectors vulnerable to identical failure points. As BBC News reported, independent experts warned that the incident serves as a stark reminder of this extreme systemic concentration. When one provider stumbles, unrelated enterprises face instant communication paralysis simultaneously.
Market convenience often encourages executives to bundle email, video conferencing, and file storage under one vendor account. That decision reduces procurement overhead, yet it magnifies vulnerability during unexpected service failures. Can your daily operations survive if your primary vendor abruptly disconnects your corporate access?
- Establish off-grid protocols: Secure independent communication accounts outside your primary software provider so executive teams can exchange messages during global cloud failures.
How Can Organizations Protect Daily Workflows During Future Incidents?
Organizations preserve operational continuity during large vendor outages by maintaining alternative communication paths that do not share underlying cloud backbones. The New York Times noted that recovery efforts showed encouraging progress only after extended engineering work. Having a documented crisis response workflow ensures employees switch immediately to alternate channels without waiting for vendor announcements.
In our experience, teams lose valuable time simply debating whether an outage is local or global. Clear triage protocols save that time. Staff members switch immediately to designated backup messaging platforms or telephone trees the moment administrative portals drop offline, keeping client deliveries moving forward.
- Train response teams: Run regular rehearsal drills where staff practice coordinating project deadlines using emergency offline channels and secondary phone rosters.
FAQ
How long did the Microsoft service outage last?
The service interruptions disrupted critical corporate tools across two days before technicians stabilized system routing. The New York Times confirmed that recovery operations showed encouraging progress after widespread connectivity issues disabled email delivery and collaborative messaging platforms for global clients.
What official response did Microsoft provide following the event?
Microsoft stated that it was deeply sorry for the incident while engineers worked through recovery phases. BBC News reported that the firm highlighted broad restoration across affected systems as technicians addressed backlogs within enterprise messaging and identity verification services.
What lesson should business leaders take from this disruption?
Technology analysts stressed that the collapse provides a stark reminder of systemic reliance on a tiny group of dominant infrastructure providers. Organizations must build redundancy across disparate networks rather than entrusting critical daily operations entirely to an individual software vendor.
Technological resilience requires deliberate preparation rather than blind trust in global cloud vendors. As enterprise platforms recover and systems return to normal operation, forward-thinking organizations will review their internal dependencies and build resilient backup channels to safeguard everyday communication.
Stay informed with accurate, up-to-date global news coverage.
Sources
- Microsoft 'deeply sorry' for global outage as it reports broad recovery (BBC News): https://www.bbc.co.uk/news/articles/c6rrg51rkz09o?at_medium=RSS&at_campaign=rss